c-84, sector 65, Noida
A Hebrew Scripture publisher moved from manual database uploads to an AI pipeline generating transliteration via OpenAI across English and Spanish verses.
The Client publishes a complete Hebrew Scripture canon to an English and Spanish reading audience worldwide, with phonetic transliteration that lets readers unfamiliar with the Hebrew alphabet follow the original pronunciation on the page. The engagement sits in a thin field. Programmatic Hebrew to Latin transliteration at the scale of a complete canon, generated through an AI model under a Client authored rule set and shipped on a reading surface for a lay audience, has few comparable precedents in Hebrew Scripture publishing. At engagement open, every verse update to the live reading surface began with a database statement assembled by hand and routed through engineering before it reached a reader, which placed the publishing cadence on engineering turnaround and held the editorial team one step removed from the reader. Clixlogix worked directly with the Client’s technology head across the engagement and designed an editorial pipeline that moved publishing control onto a workflow the Client’s team runs from the admin, with the full pipeline sitting on an OpenAI integration for the Hebrew transliteration leg and later for the Spanish translation leg. The engagement ran across 5 stages of design and build and closed with a complete canon live in English and Spanish, chapter level audio on every chapter page, and a Client editorial team that publishes new content without engineering intervention on each change.
The Client is a multilingual publisher of Hebrew Scripture content, headquartered in the United States and reaching readers worldwide. The reading audience spans denominational traditions, and now includes Spanish readers reached through the Spanish surface shipped in the final stage of the engagement.
The Client’s publishing mission anchors on the authoritative Hebrew source text. Each verse carries phonetic transliteration prepared so readers who do not read Hebrew letters can follow the original pronunciation on the page, which places the Client’s reading surface as a point of entry into the Hebrew canon for an audience without Hebrew literacy. The transliteration rule set is a Client authored specification held and iterated inside the admin, so wording decisions on how the pronunciation renders in Latin script sit with the Client’s editorial team, outside the cataloguing standards or a vendor product. The combination of an authoritative Hebrew source, an AI model generating reader facing transliteration against a Client specification, and a full canon shipped bilingually from one editorial pipeline places the Client’s platform in a thin corner of Hebrew Scripture publishing.
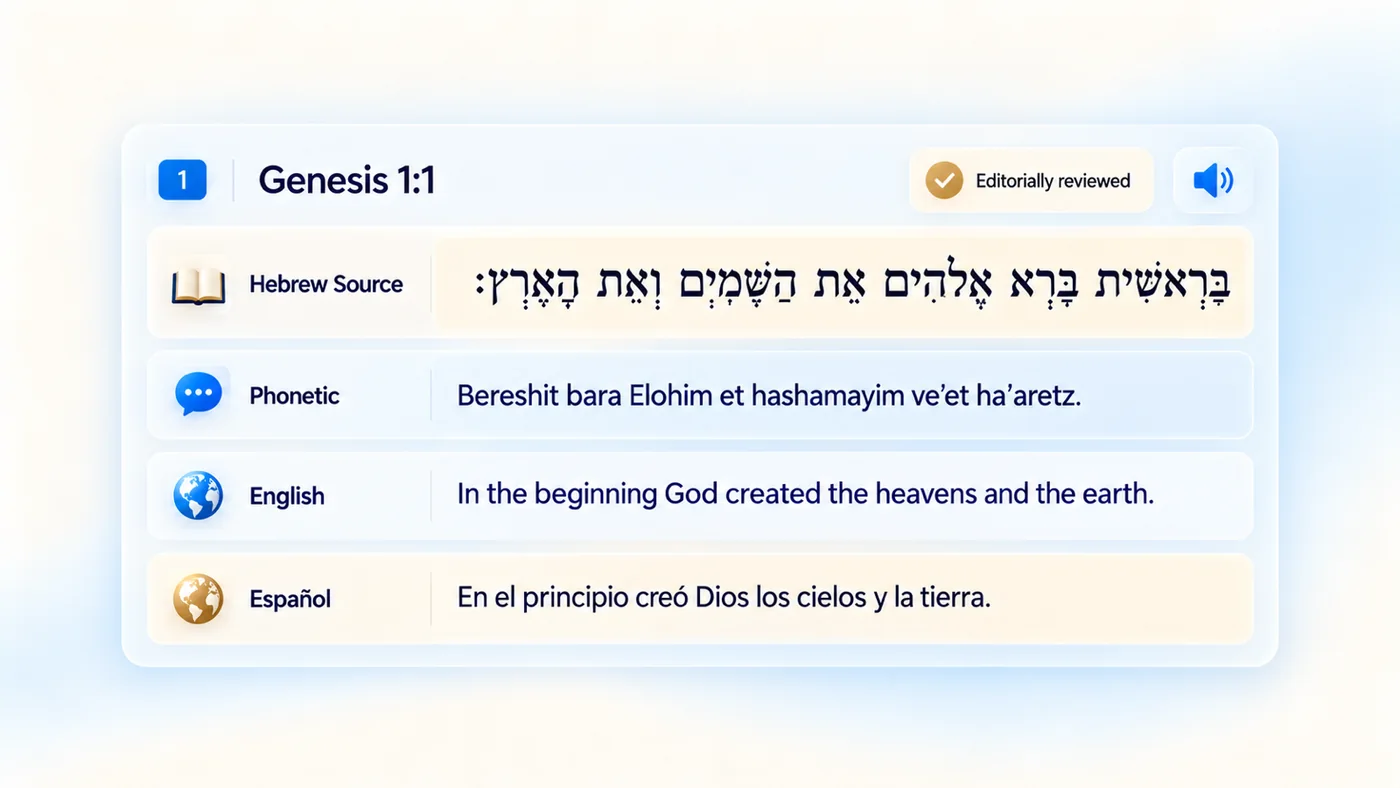
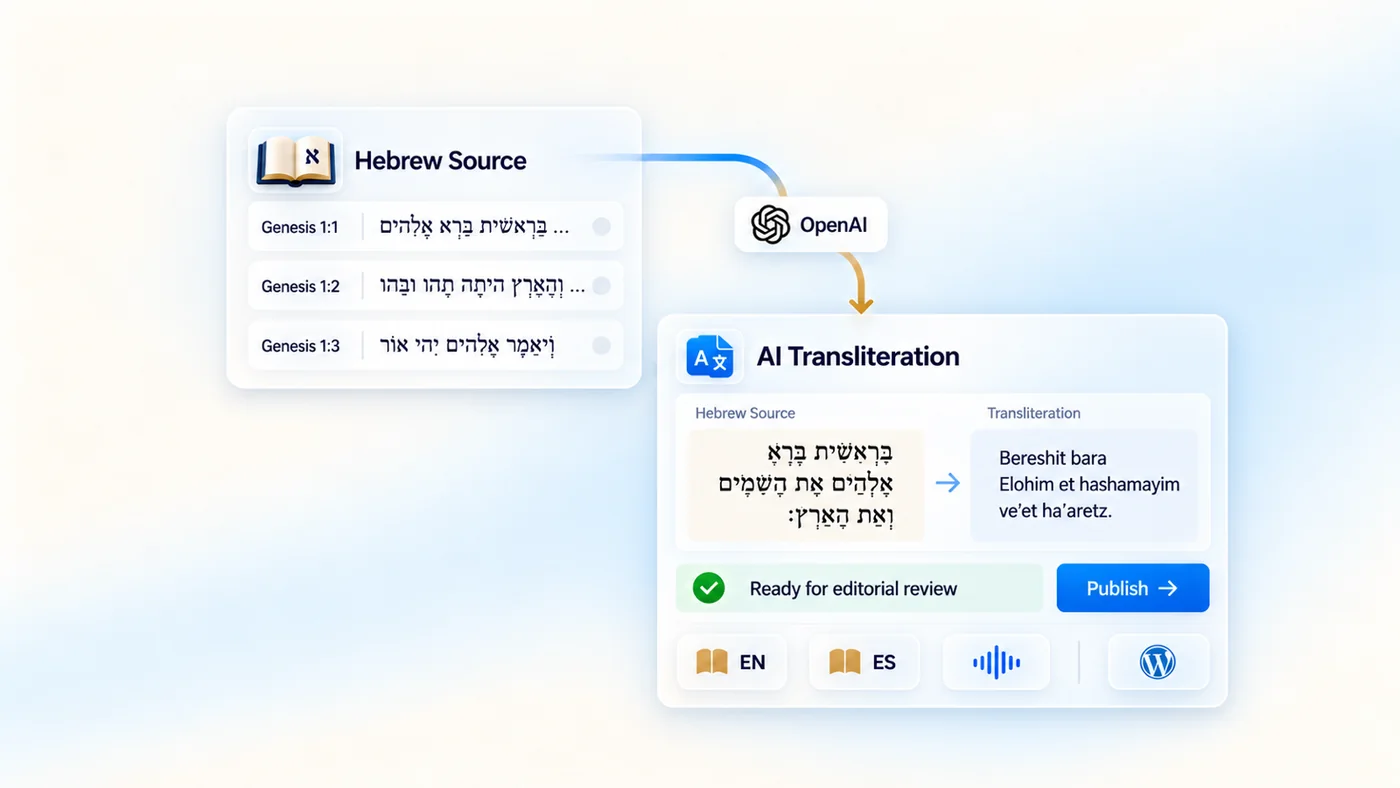
Fig 1 - The reading surface output for a single verse across four content lines
Design discipline on the reading surface runs on a system the Client defined in Figma and holds under its own stewardship. The verse page, the chapter listing, the breadcrumb, the side navigation, and the search surface sit inside one visual language the Client controls directly. Latin script headings and Hebrew text sit alongside each other on the page under a defined typography treatment.
The Client’s technology head, working from Haifa, Israel, owned the technical direction across the engagement and was the Clixlogix counterpart on every architectural and operational call. The engagement ran as a long form, 5 stage programme of design and build, which signals a durable platform investment on the Client’s side and places the publishing surface as a strategic asset the Client will carry forward over years.
The Client had access to the raw ingredients of a modern scripture publishing system. The authoritative Hebrew text was available through an open scripture API. An AI model was available to generate transliteration under a Client authored rule set. A WordPress reading surface already existed. The problem was not a missing ingredient. The problem was that nothing connected the ingredients into a workflow the Client’s editorial team could run on its own.
Three architectural problems defined the engagement.
Editorial control sat outside the editorial team - Every content update began with a database statement assembled by hand and routed through engineering before it reached the reader. The Client’s technology head described the workflow in these words.
The client’s technology head, on the workflow at engagement open
“I have direct access to the database so I can send you an SQL which you can update and then I can manually upload back into the website.”
The workflow cost engineering hours on every content change and kept the publishing cadence inside the database, outside the editorial calendar.
No single pipeline connected source to published surface - The Hebrew source API, the AI model, and the production database each existed as separate reachable systems. No component owned the loop that reads the source for a given verse, calls the model for the transliteration, writes the record into the correct taxonomy, and surfaces the operation to the editor who triggered it. The absence of that owning component is what forced the manual workflow in the first place.
No tenancy model for additional reading languages - The content programme ran in one language. A second language variant with its own URL namespace, taxonomy mapping, and language switcher had no architectural path. Reaching a second reading audience would have required a second content programme at engagement open, because the existing one could not be configured to carry it.
The engagement opened on these three problems and defined the architectural response against them.
| Operational axis | Before engagement open | After engagement close |
|---|---|---|
| Content ingestion into the live reading surface | Database statements assembled by hand, routed through engineering, uploaded to production on every change | Editorial pipeline triggered from the admin, iterating books, chapters, and verses programmatically |
| Hebrew source retrieval | External to the production surface, reached by hand for individual updates | Queried verse by verse inside the pipeline, bound to the production record on write |
| Transliteration generation | Not operational at canon scale | AI model called per verse against a Client authored rule set, output written to the publication record |
| Reading languages live on the surface | One, with partial coverage | Two, with the complete canon live in English transliteration and Spanish translation |
| Multilingual URL structure | Not present | /es/ URL namespace with language switcher mapping each English record to its Spanish counterpart |
| Chapter level audio | Not available on the reading surface | Audio reads integrated on every chapter page across the canon |
| Hosting arrangement | Prior host with configuration friction on long running operations | Managed hosting partner carrying the production environment and the database engine upgrade path |
Table 1 - Operational axes that transformed across the engagement
The engagement ran across 5 consultative stages. Each stage closed on a deliverable set the Client could use before the next stage opened.
Clixlogix opened the engagement with working sessions on what the Client’s editorial team actually needed to do and what the system had to carry. The sessions converted a general description of a “plugin” into a named set of pipeline responsibilities, a data flow, an admin surface, and a failure model. The architecture decisions on pipeline ownership, transliteration generation, multilingual URL structure, and hosting all landed during this stage.
At the end of this stage the Client owned an architectural diagnosis naming the three problems, a pipeline design naming the responsibilities and their data flows, and a decision record naming the alternatives considered on each architectural call.
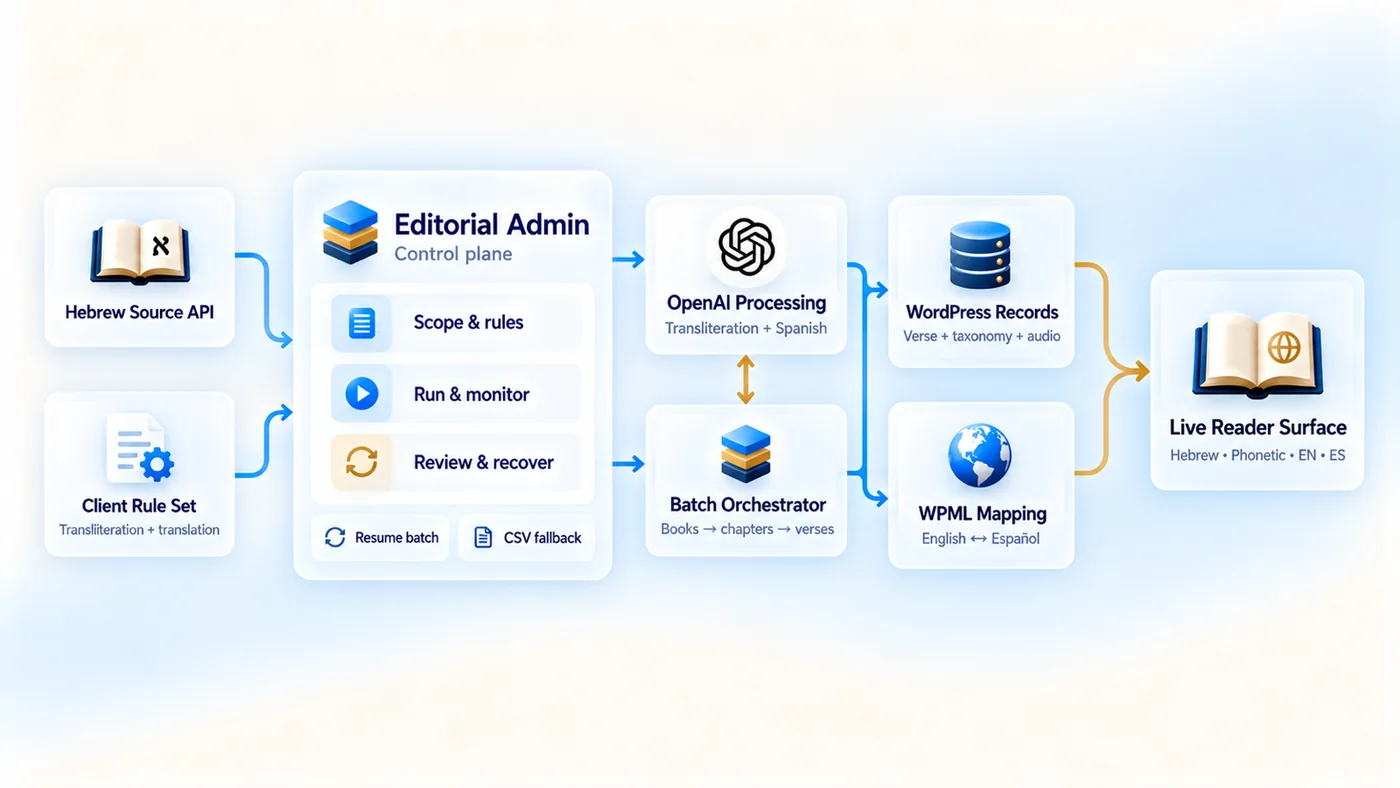
Clixlogix built the pipeline that reads Hebrew source text for a given verse, generates the English transliteration through the AI model under the Client authored rule set, writes the result into the correct publication tables with the correct taxonomy relationships, and surfaces the operation state to the editor through the admin. The stage shipped a CSV export fallback so the Client’s team could review and reinsert content if a batch failed in the middle of a run. The pipeline closed with a run across the full Old Testament canon.
At the end of this stage the Client owned a working editorial pipeline across the full canon in English, an admin surface for triggering and recovering runs, and a CSV export fallback as a second recovery path.
Fig 2 - System architecture with the editorial admin as the control plane for AI assisted Scripture publishing
The Client supplied a design system covering the verse page, the chapter listing, breadcrumbs, side navigation, button states, and verse level typography. Clixlogix implemented the design system in WordPress templates, bound each template to the pipeline’s data model, and added shortcodes for verse rendering, in site search, and collection pages. Latin script headings and Hebrew text rendering landed in the typography layout. Chapter level audio uploads landed during this stage and the plugin surfaced the audio reads on the chapter page template.
At the end of this stage the Client owned a reading surface aligned to the design system, a chapter page carrying integrated audio, and the shortcode set for the verse, search, and collection pages.
Clixlogix moved the production environment to a managed hosting partner and stabilised the operational issues the Client was carrying. Clixlogix resolved the taxonomy mapping drift during content writes by moving the taxonomy write to run only after the verse record is confirmed. Clixlogix addressed the server side execution limits on long running ingestion batches by splitting the pipeline’s work into bounded jobs with persisted state between runs. Clixlogix hardened the image handler against malformed source responses. A database engine version upgrade on the hosting side blocked content updates for a period during this stage. Clixlogix reconciled the pipeline’s database access path and the hosting partner reconciled the host side configuration against the upgraded engine, after which content updates resumed.
At the end of this stage the Client owned a hardened production surface, an incident log naming each stabilised issue with its resolution, and a hosting arrangement that isolates engine upgrades from the pipeline work.
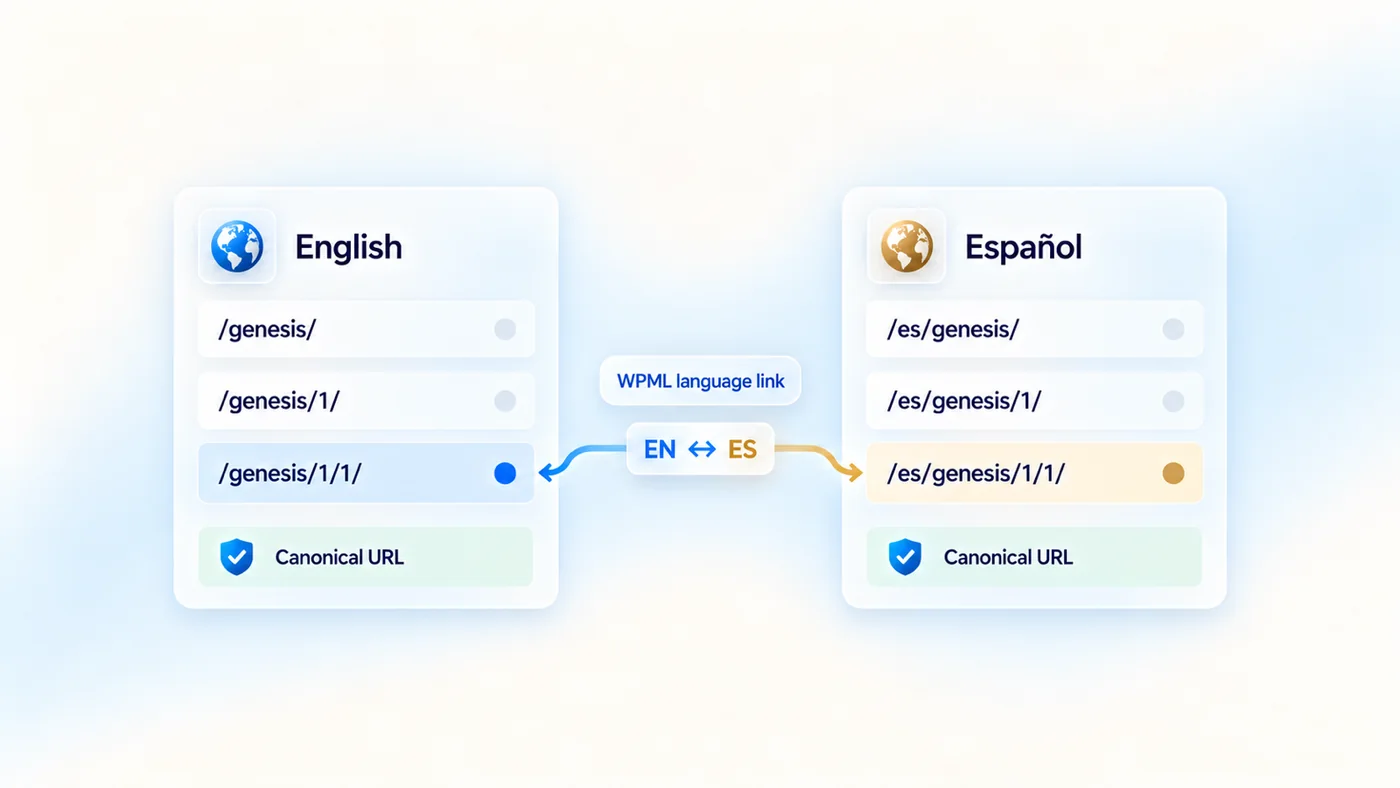
Clixlogix extended the pipeline to Spanish. The Client reviewed existing Spanish language Jewish Bible translations and found them insufficient for the reading surface. Clixlogix added an AI translation path that reads the English verse and writes the Spanish verse into the publication record under a Spanish language variant. WPML carried the /es/ URL namespace, the language switcher on each verse page, and the taxonomy mapping between the English and Spanish records. The engagement closed with transition sessions handing the admin workflow and the recovery paths to the Client’s editorial team.
At the end of this stage the Client owned a complete Hebrew Scripture canon live in English and Spanish, a multilingual URL structure served by WPML, and the operating knowledge to run the pipeline, edit the transliteration rule set, and recover from a partial batch failure without engineering support.
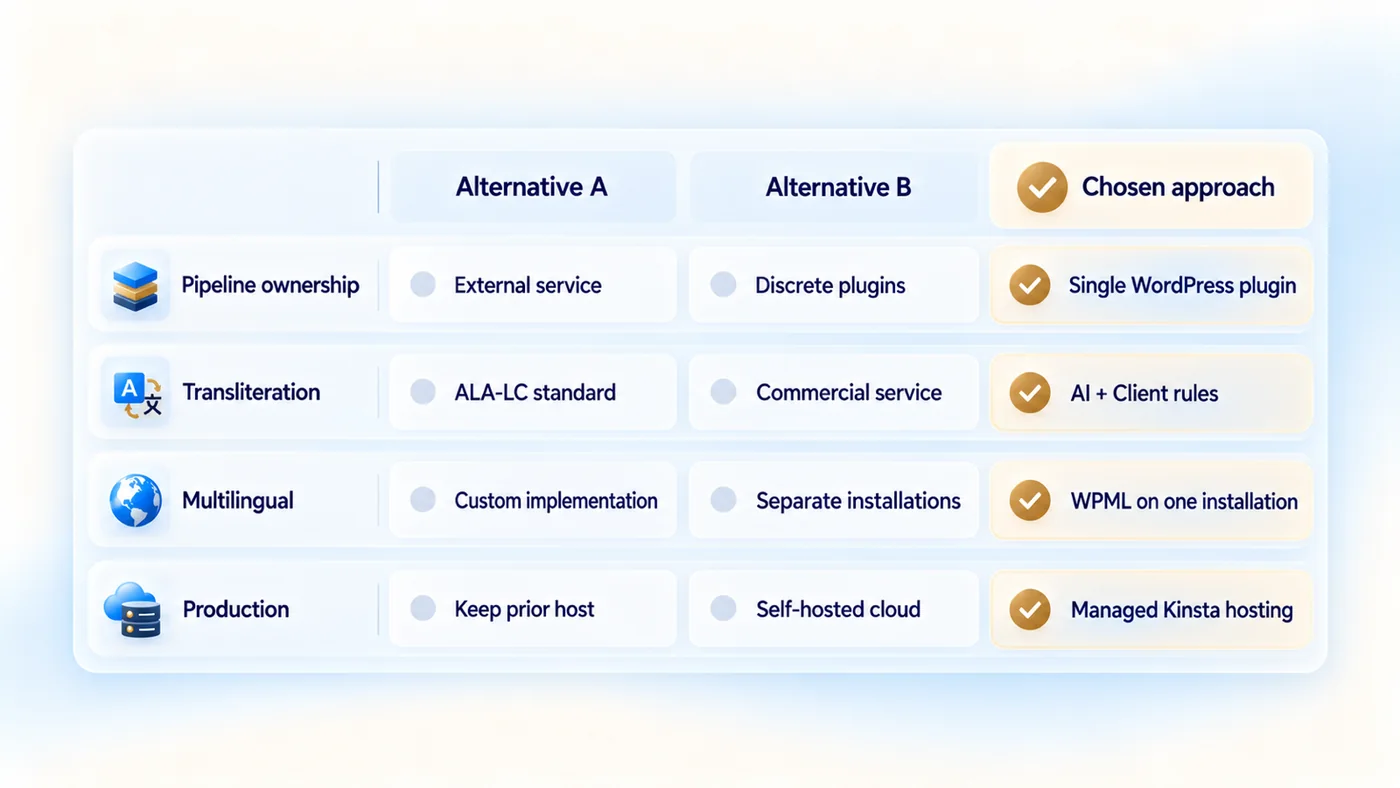
Fig 3 - The alternatives Clixlogix evaluated across the four architecture decisions
The decision had to minimise the number of surfaces the Client’s editorial team touches to run and recover a pipeline operation, and had to keep failure recovery inside the environment the Client already uses.
The single plugin option placed the pipeline inside the surface the Client’s team already uses for every other content operation. The thin plugin plus external service option split the operating surface across two environments and created a second failure mode on the integration between them. The discrete plugins option fragmented ownership of responsibilities that only make sense together. The single plugin design kept the operating surface and the failure recovery surface inside one environment and preserved the CSV export as a second recovery path.
The decision had to produce a Latin script form a lay reader can pronounce without diacritics and had to keep the rule set editable by the Client without a code release on every revision.
The ALA-LC Hebrew and Yiddish romanization table approved by the Library of Congress and the American Library Association is engineered for reversibility back to the Hebrew source for scholarly cataloguing. A reading surface that targets an audience without Hebrew literacy carries a different design constraint; the transliteration must approximate pronunciation on the page without requiring the reader to interpret ḥet, qoph, or shewa marks. The commercial transliteration option kept the rule set locked inside the vendor’s product. The AI model option under a Client authored rule set kept the specification inside the Client’s control and allowed the Client’s team to iterate wording without a code release.
Transliteration Standards
The ALA-LC Hebrew and Yiddish romanization table approved by the Library of Congress and the American Library Association is the dominant Latin script convention for Hebrew in library cataloguing worldwide. Its 2011 revision (ALA-LC Romanization Tables at loc.gov) is engineered for reversibility back to the Hebrew source for scholarly search, which places diacritics and consonantal mappings that a lay reader finds unfamiliar. A reading surface that targets an audience without Hebrew literacy carries a different design constraint. The engagement treated the Client authored rule set as a reader facing specification, which positions the output outside the cataloguing standard and inside a reading specification the Client owns and iterates.
Fig 4 - The content pipeline from authoritative Hebrew source to published verse page
The decision had to carry the Spanish surface on the same canonical URL rules the pipeline already enforced on English and had to preserve search engine resolution of each language variant.
The custom implementation would have reinvented a problem a mature tool already solves and would have placed URL rewriting on the pipeline’s maintenance surface. The separate installation per language would have duplicated the operating surface and forced the Client’s team to maintain two environments. WPML kept the Spanish surface on the same installation, mapped each English record to its Spanish counterpart, and preserved the plugin’s canonical URL rules so search engines resolve each language variant correctly.
Fig 5 - The multilingual URL structure under WPML
The decision had to isolate database engine upgrades, PHP runtime management, and asset delivery from the pipeline work, so the two operational tracks could run on separate cadences.
The prior host left the Client inside the configuration friction the engagement was trying to retire. The self hosted option gave full control but moved runtime management onto the Client’s own operations. The managed hosting option placed runtime management on a partner whose job is runtime management, which freed the pipeline work from the hosting work on an ongoing cadence.
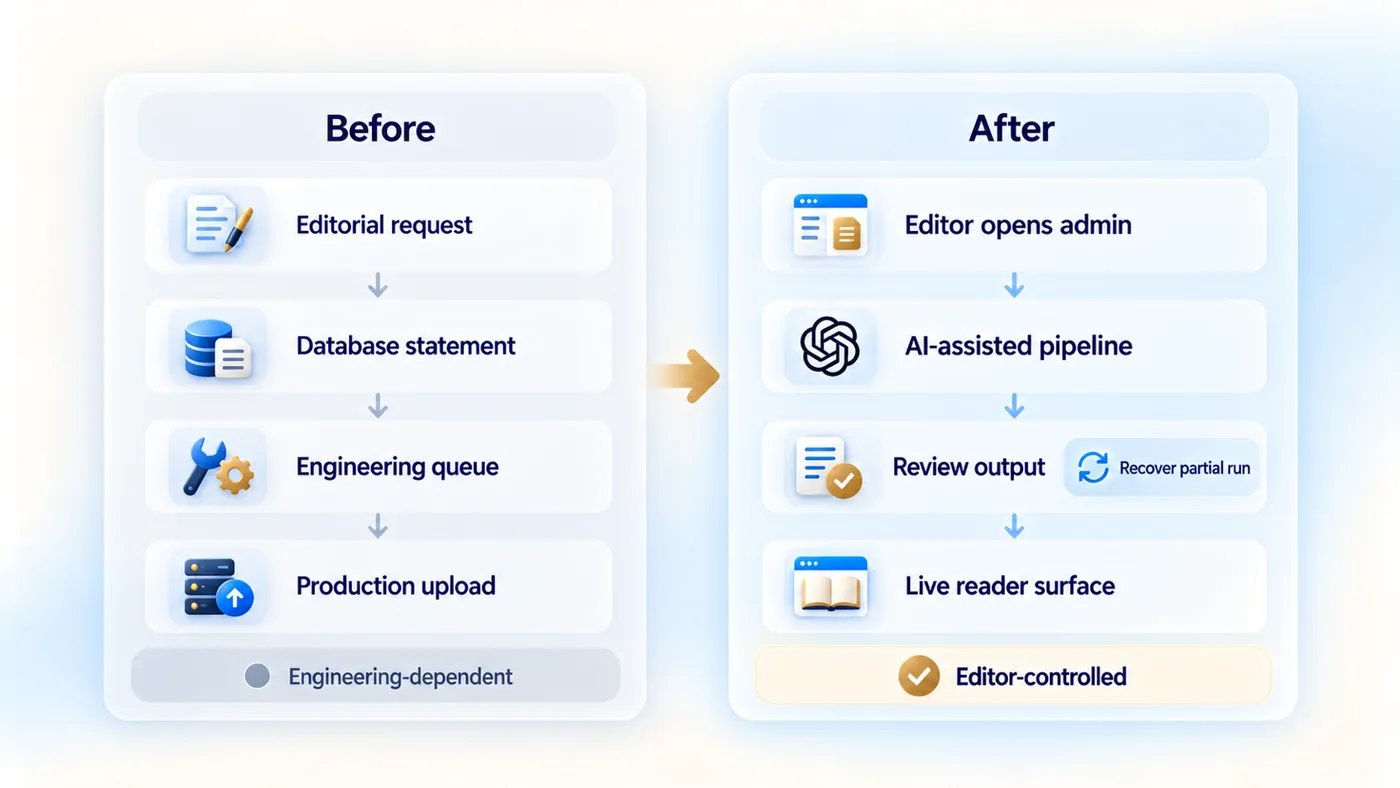
The editorial team began the engagement outside the publishing path. Every content update required an engineering intervention, which placed the cadence of the reading surface on engineering turnaround and the quality of the content behind a serialised review step. Clixlogix built the pipeline so the editor who initiates an update is the operator who runs the pipeline, reviews the output, and sees the result on the live surface, with the recovery path from a partial failure available on the same admin screen. The admin now carries full publishing capability and the Client’s editorial team operates the pipeline on its own cadence.
Fig 6 - The publishing workflow before and after the engagement
The reading surface at engagement open did not reflect a design system. The Client’s design system defined the verse page, the chapter listing, breadcrumbs, side navigation, button states, and verse level typography, and specified how Hebrew and Latin scripts render alongside each other. Clixlogix implemented the design system in WordPress templates, bound each template to the pipeline’s data model, and added shortcodes for verse rendering, in site search, and collection pages. The reader now meets a surface that respects the Client’s design system across every verse, every chapter, and every collection.
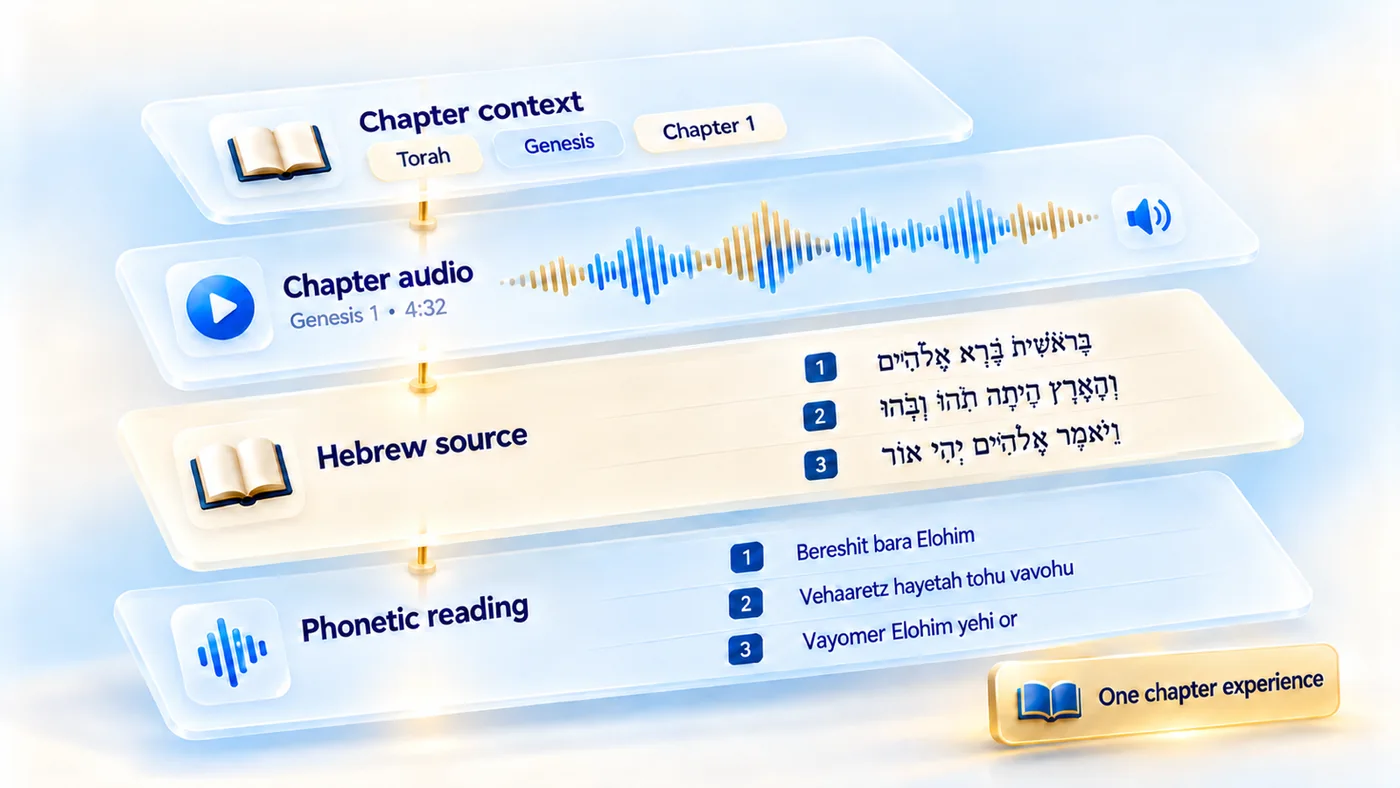
The Client was carrying three production issues when the engagement opened the production stabilisation stage. Verse pages intermittently returned 404 when a write failed partway through a chapter and the taxonomy mapping drifted from the verse record. Long running ingestion batches hit server side execution limits before the chapter completed. The image handler threw JSON parsing errors on malformed source responses, which affected article images on specific pages. Clixlogix moved the taxonomy write to run after the verse record is confirmed, split the pipeline’s work into bounded jobs with persisted state between runs, and hardened the image handler against malformed source responses. Chapter level audio uploads landed during the design alignment stage and the plugin surfaced the audio reads on the chapter page. The reader now meets a hardened reading surface with audio on every chapter page.
Fig 7 - The chapter reading experience as four integrated layers of context, audio, Hebrew source, and phonetic reading
The Client reached one language community at engagement open. A second language variant with its own URL namespace, taxonomy mapping, and language switcher had no architectural path on the existing system. The Client reviewed existing Spanish language Jewish Bible translations and found them insufficient for the reading surface. Clixlogix added a Spanish translation path that reads the English verse and writes the Spanish verse into the publication record under a Spanish language variant, with WPML carrying the URL namespace and the taxonomy mapping. The reading surface now serves the Spanish community on the same canon through the same pipeline.
Linguistic Reach
Instituto Cervantes publishes an annual report on the global demographics of the Spanish language through its Global Observatory of Spanish. The 2025 edition (Spanish, a language to the world 2025 at observatoriodelespanol.cervantes.org, Table 4) records 519,115,258 native speakers and 635,743,644 total potential speakers, counting native, limited competence, and learners. The current market context for the Client’s Spanish surface is a global reading community of this scale. The publishing economics of a second language variant settle at the ongoing cost of running the pipeline once per language. A second content programme is not required.
Fig 8 - The engagement stage sequence from Diagnose through Transition
| Area on this engagement | Technology | Role across the engagement |
|---|---|---|
| Authoritative Hebrew source retrieval | Open scripture API | Hebrew source text pulled verse by verse during pipeline runs |
| AI processing path for transliteration and translation | AI chat completions API | English transliteration generation in stages 2 through 4, Spanish translation generation in stage 5 |
| Content management and reading surface | WordPress | Reading surface, admin workflow, template rendering, and shortcode library |
| Full publishing pipeline runtime | Custom WordPress plugin authored by Clixlogix | Canon iteration, Hebrew source retrieval, transliteration and translation generation, publication record writes, taxonomy enforcement, retry handling, admin surfacing |
| Multilingual delivery across language variants | WPML | /es/ URL namespace, language switcher, taxonomy mapping between English and Spanish records |
| Managed hosting partner carrying production | Kinsta managed hosting | Production environment from stage 4 onward, database engine upgrade path, PHP runtime management, asset delivery |
| Typography across Latin and Hebrew scripts | Proxima Nova, adobe-hebrew | Latin script headings and Hebrew text rendering across the reading surface |
| Design system supplied by the Client | Figma | Design system defining the verse page, chapter listing, breadcrumb, side navigation, and search surfaces |
Table 2 - Technologies and tools across the engagement
Our team can share client references, scope your project, and answer any question about your delivery.
More engagements where our delivery teams shipped similar outcomes for clients across industries. Read on for context on the patterns we reused, the trade offs we navigated, and the metrics that landed in production.