Living document
OpenAI has not yet published the full Decisions API schema, pricing, or preview technical documentation. This article is based on the DevDay 2026 announcement and vendor pages available at the time of writing. We will update it as OpenAI releases official documentation, and again once independent evaluations begin to appear.
Published September 30, 2026. Last updated September 30, 2026.
TL;DR
- OpenAI Decisions API was announced 8 days after Clixlogix’s Jev guide. The interfaces overlap. The implementation details do not.
- OpenAI has not published pricing, response schema, abstention behaviour, or whether probabilities are exposed. Jev has published all of these.
- GPT-6 Luna already supports Structured Outputs with a JSON Schema enum, so fixed answer JSON is not new. The open question is whether Decisions API adds calibration, latency, or economics on top of that.
- Jev’s edges are specialised training, transparent input pricing with free output, and availability across several providers today. OpenAI’s edges are image input, distribution, and integration across its agent ecosystem.
- The comparison that matters is calibrated probability quality, abstention behaviour when no answer fits, and cost per successful decision measured on production data.
- If your team is already paying general LLM prices for routing, classification, scoring, or approval calls, OpenAI and Jev are now 2 prominent hosted options. The right choice is workload specific.
Clixlogix published its guide to the Jev AI decision model on September 21, 2026. 8 days later, OpenAI announced Decisions API at DevDay.
DevDay 2026 also included Codex expansions, security scanning, and other developer tooling updates. Decisions API is the announcement most relevant to teams already thinking about specialised decision models.
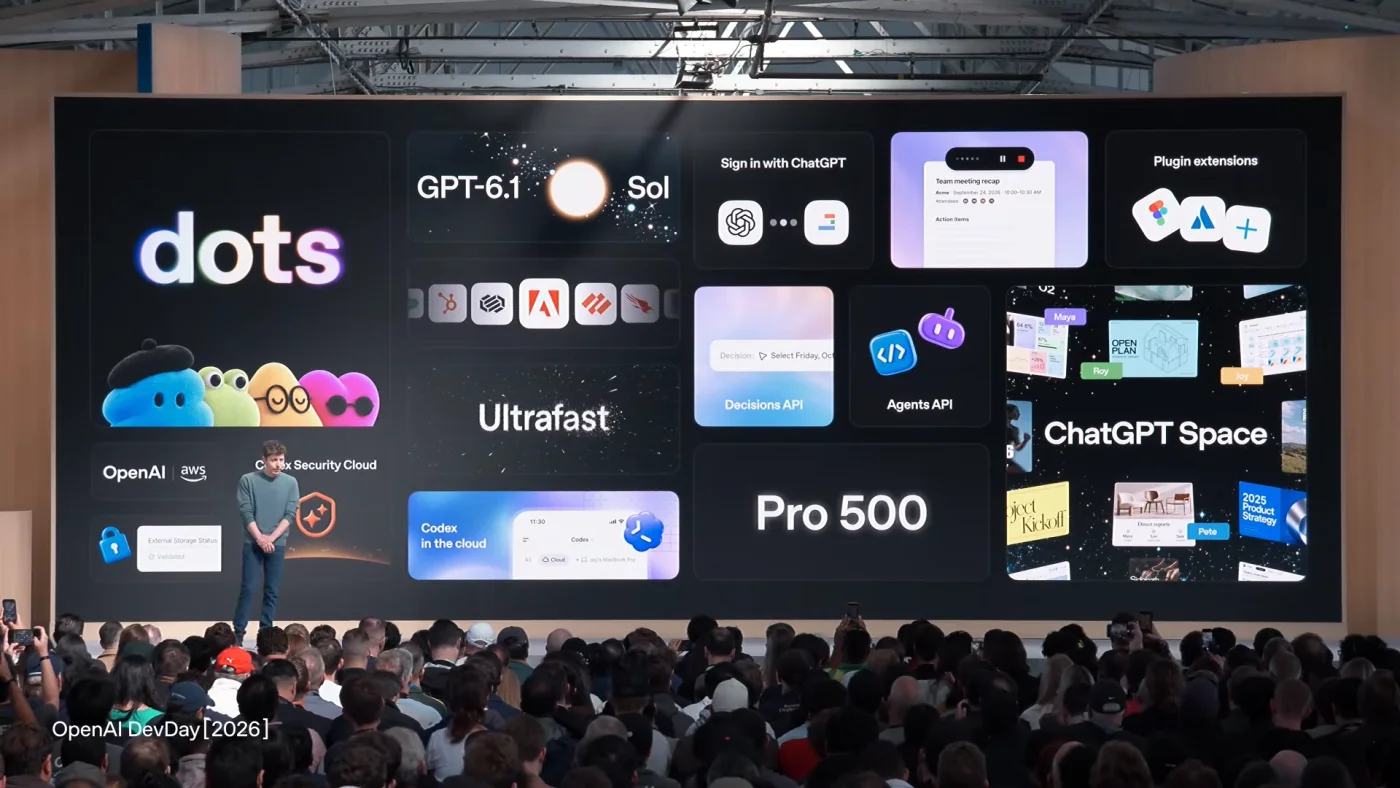
Fig 1 – OpenAI presented Decisions API during DevDay 2026 alongside its broader developer platform announcements. Image: OpenAI DevDay 2026
The timing brings decision models into a much larger conversation.
OpenAI describes Decisions API as a service for classification, request routing, and agent action selection. Developers define questions and possible answers, then supply text or images as context. The API returns answers that the application can use. The service is powered by GPT-6 Luna. Access has started through a limited preview, with broader availability planned in the coming days.
This places OpenAI in direct competition with Jev for bounded decisions inside software and AI agents.
What OpenAI Decisions API does
Many software workflows require a choice from a known set of outcomes.
These situations run through most software systems:
- Support routing - A ticket goes to billing, technical support, account management, or an escalation queue.
- Transaction risk - A payment is classified as clear, hold, or block.
- Content moderation - A piece of user content is marked allow, warn, restrict, or remove against a defined policy.
- Agent tool calls - A proposed tool call is approved, denied, or sent for human review.
- Agent planning - A multi step agent picks its next step from a fixed set of tools or planning branches.
The same kind of bounded decision runs through the wider business stack:
- Sales - Inbound leads are qualified and routed to the right owner.
- Finance - Invoices are approved, held, or rejected before entering the payment queue.
- Compliance - Policy checks resolve to pass, fail, or review.
- Ecommerce - Product listings are assigned to a category before indexing.
- Insurance - Claims are triaged into automated processing, adjuster, or fraud review.
OpenAI Decisions API is designed for these situations.
The developer defines the decision before sending the request. The model receives the available context and evaluates the permitted answers. The application receives an answer that can trigger the next step. This is a more controlled task than general text generation. The application already knows which outcomes it can accept. The model supplies the judgment required to choose among them.
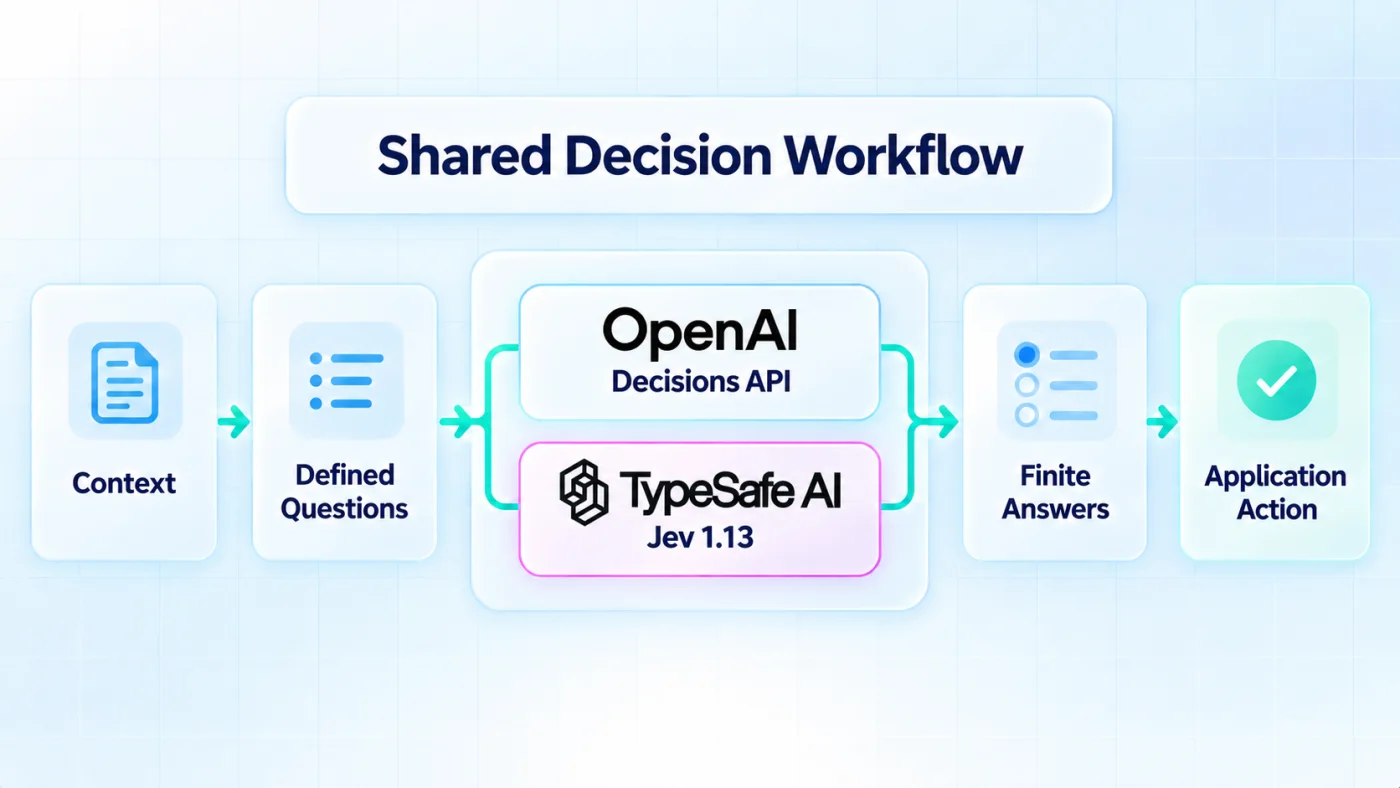
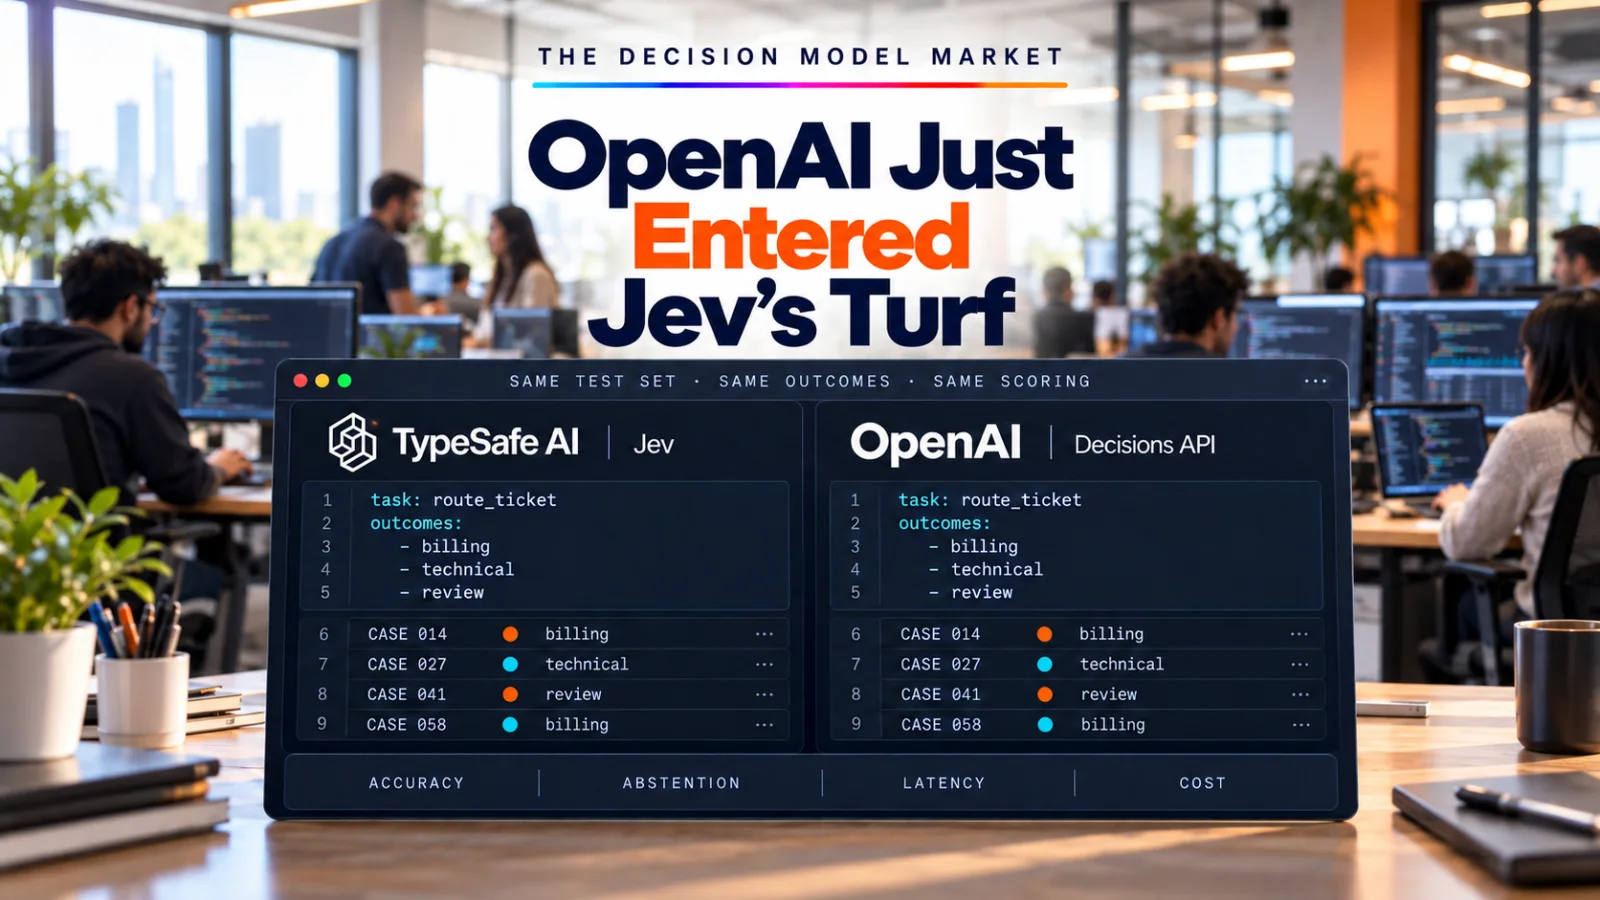
Fig 2 – OpenAI Decisions API and Jev both turn supplied context into bounded answers that software can use. OpenAI and TypeSafe wordmarks are trademarks of their respective owners
At the time of publication, the public OpenAI API reference has yet to provide a Decisions API endpoint, complete request format, pricing, limits, or response schema.
Table 1 – The announced interfaces overlap, while several important OpenAI implementation details remain unpublished
Why fixed answers matter
The defined answer set is one of the most important parts of a decision interface.
A standard GPT-6 Luna request can already return schema constrained output containing a fixed set of values through Structured Outputs and a JSON Schema enum. Decisions API packages this task into a dedicated interface. Its practical value will depend on whether it improves accuracy, calibration, latency, cost, or evaluation compared with Luna using Structured Outputs.
A decision interface declares the available answers before the request is evaluated and returns an answer from that defined set. The result can be evaluated against a stable contract.
This creates several practical benefits.
- Responses can be constrained to an approved set of outcomes.
- Test cases can use the same answer set as production.
- Accuracy can be measured consistently.
- Individual decision types can carry separate thresholds where the provider exposes a suitable numeric signal.
- A declared output contract can keep selections within the permitted set when the surrounding prompt changes, although the selected answer may still shift.
- Applications can connect each outcome to an explicit action.
A fixed answer set also improves evaluation quality. A team can build a dataset with known outcomes and measure how often each model selects the correct answer. The same dataset can test Jev, OpenAI Decisions, rules, classifiers, and general language models.
The technical question OpenAI still needs to answer
OpenAI says Decisions API is powered by GPT-6 Luna. The company has yet to explain how the decision behaviour is produced.
Several implementations are possible.
The service could use specialised training, constrained decoding, whole answer candidate scoring, a classification component, or a managed Luna request with a dedicated response contract. Each approach would have different implications for accuracy, calibration, latency, and cost.
This distinction matters because Jev presents itself as a dedicated decision model. TypeSafe describes Jev as using Reinforcement Learning for Calibrated Decisions (RLCD), along with an architecture designed to evaluate multiple typed questions efficiently.
If OpenAI uses a general language model behind a controlled interface, Jev may retain advantages that come from specialised training. If OpenAI has adapted Luna specifically for decision workloads, the competition becomes much closer.
The documentation and independent testing will need to establish the answer.
A decision system needs a way to abstain
A fixed set of answers creates a difficult edge case. The supplied context may fit none of the available options.
Consider a support router with 4 destinations, billing, technical support, account management, and abuse review. Those 4 cover almost everything that arrives, which is exactly why the gap is easy to miss until it appears in production.
A legal request or media enquiry falls outside that set. Forcing the model to choose one of the 4 creates a valid response with an invalid meaning.
A production decision service needs a defined way to handle this situation. The mechanism matters more than it first appears, because the alternative is a service that always answers and never signals that it was guessing.
- An abstain result - The model returns no answer and the request leaves the automated path. This is the cleanest option when the answer set is genuinely incomplete.
- A request for clarification - The service asks for the missing field or document before deciding. This suits workflows where context arrives in stages.
- A human review option - A named outcome that routes to a person, so the review queue becomes a designed destination with its own service level.
- A confidence threshold below which automation stops - One numeric rule per decision type, tuned from outcomes the team has already measured.
- An explicit none of these answers choice - A permitted outcome inside the answer set, which keeps the output contract closed while still admitting that nothing fitted.
Whichever mechanism a team picks, it has to be declared in the interface. A decision service that quietly returns its best guess leaves the application unable to tell a confident answer from a forced one, and that is the failure mode that reaches customers.
OpenAI has yet to describe how Decisions API handles missing, ambiguous, or conflicting options.
This detail will strongly influence its suitability for safety checks, financial approvals, healthcare workflows, moderation, and destructive agent actions.
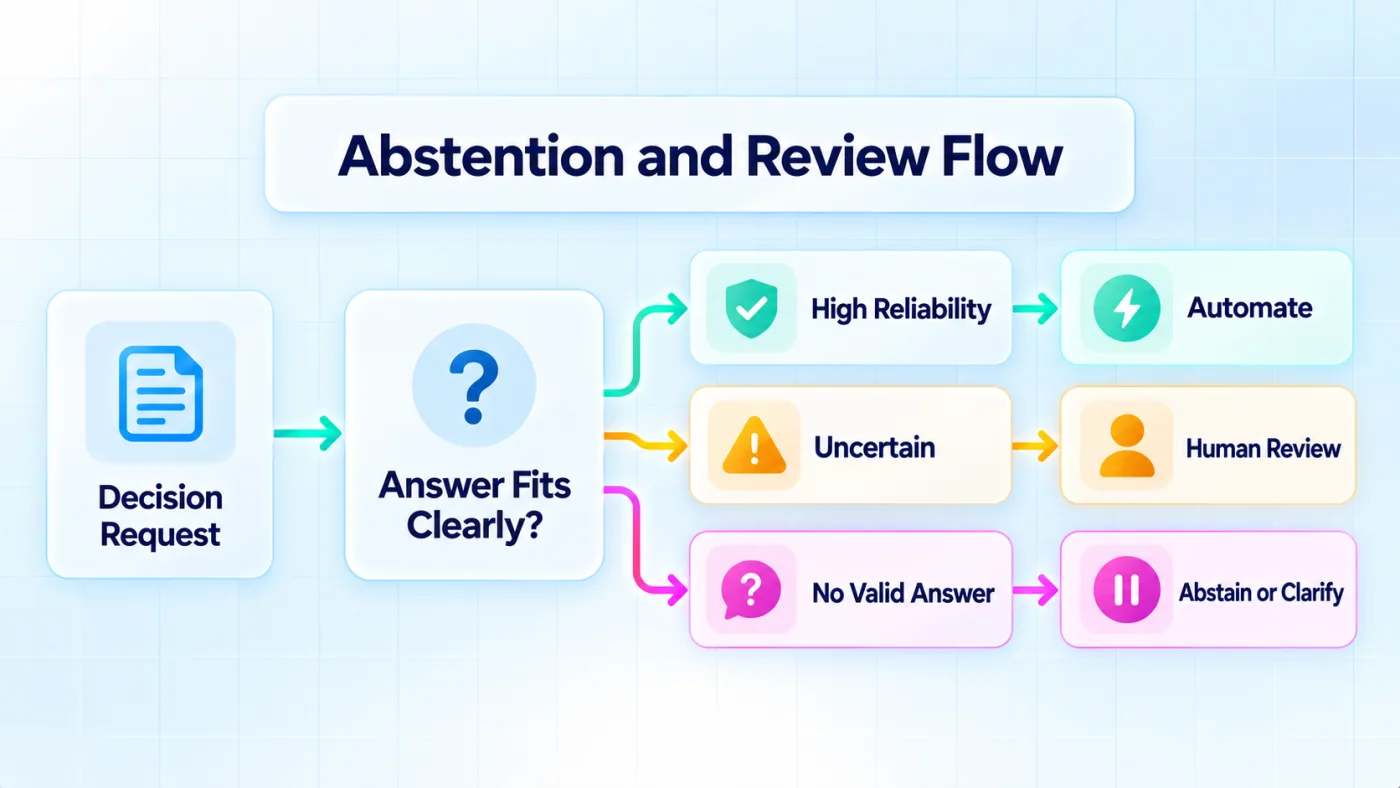
Fig 3 – Production decision systems need an explicit route for uncertainty and missing answers
A selected answer is only part of the result
Many low risk workflows can act on a selected answer alone. Higher risk decisions need additional information.
A routing system may need to know whether the preferred destination received 95 percent probability or 36 percent probability. Both calls could return the same selection, even though the appropriate workflow should differ.
The high confidence result may proceed automatically. The uncertain result may require human review.
Jev exposes probabilities as a central part of its interface, documented in both the OpenRouter guide to Jev and the Cloudflare Workers AI reference. Noul returns the probability of a true outcome. Choice returns the selected option, probabilities for the available options, and a confidence value. Score places the result on a declared scale and can include probabilities and confidence.
OpenAI has yet to confirm which of these Decisions API will expose, and the 5 options are not small variations on each other. Each one supports a different class of automation.
- A selected answer only - The minimum. Enough for low risk routing, and not enough to decide where automation should stop.
- Confidence for the selected answer - One number for the chosen option. It supports a single threshold, and it hides how close the runner up was.
- Probabilities for every available answer - The full distribution, which is what lets an application treat a 95 percent call and a 36 percent call as different events.
- Calibration information - Evidence that a stated 70 percent is correct about 70 percent of the time. Without it a probability is only a ranking.
- A recommended automation threshold - A provider supplied starting point. Useful for a first deployment, and no substitute for a threshold measured on your own traffic.
The gap between the first and the third of those decides how much of the workflow a team can safely automate. An interface that returns only a selection can still be automated, but every rule has to be inferred from outcomes over time, because the response does not carry it.
These details are absent from the announcement and the current public API reference.
Probability support will be one of the most important comparison points once the API becomes broadly available.
Calibration will matter more than confidence
A confidence value becomes useful when it reflects real outcomes across many similar cases.
If a model assigns probability 0.8 to an event across many comparable cases, that event should occur approximately 80 percent of the time. That property is calibration. A separate confidence score may describe how concentrated the answer distribution is without representing the probability that the answer is correct.
Calibration allows a product team to create meaningful automation policies. Decisions above a chosen threshold can proceed automatically. Decisions near the threshold can enter a review queue. Very uncertain decisions can stop safely.
A model can produce high confidence without being well calibrated. An OpenRouter evaluation of Jev on Banking77 found that its confidence scores were useful for ranking decisions, although they were not calibrated probabilities in that test. Teams should therefore evaluate the relationship between confidence and observed accuracy across their own data.
Jev presents calibration as a major product capability. OpenAI will need to show whether Decisions API provides comparable probability quality.
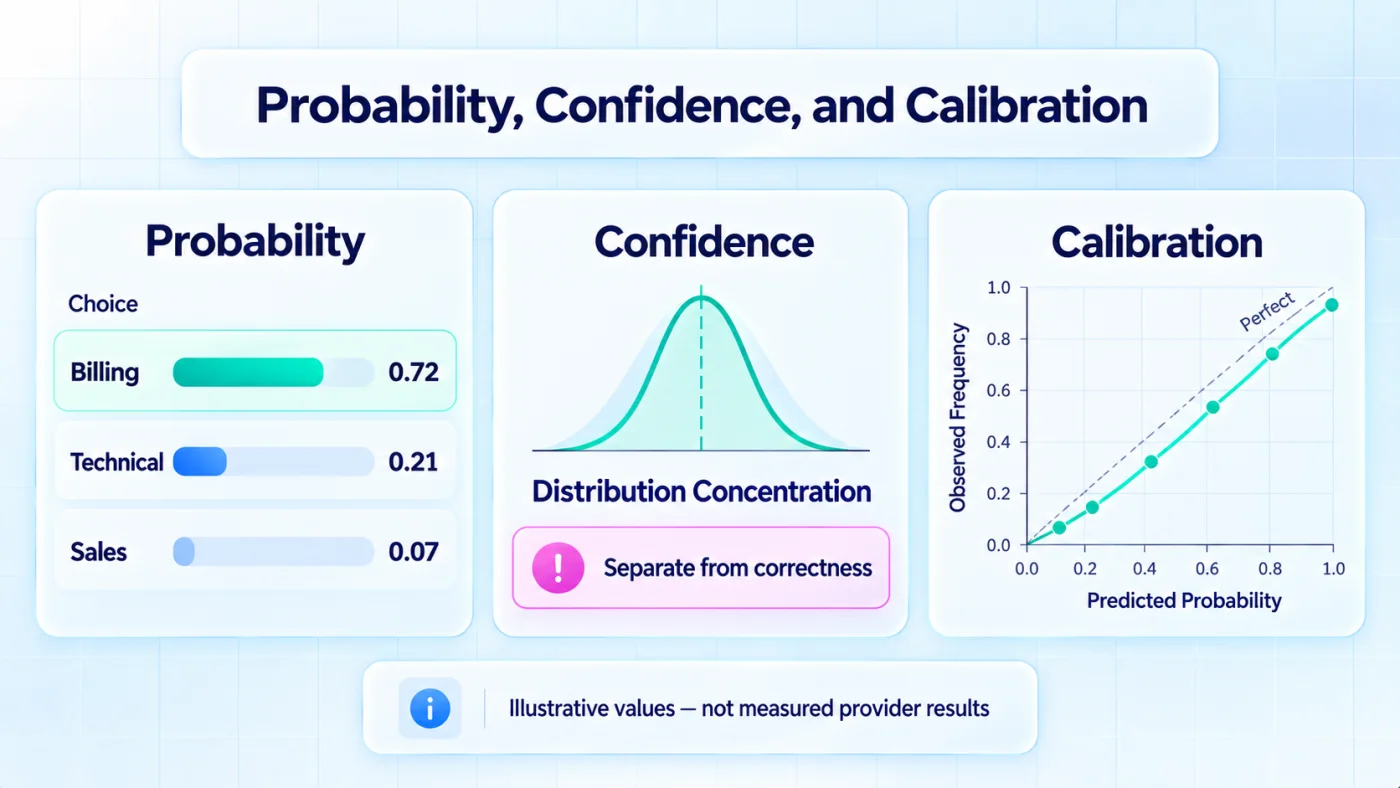
Fig 4 – Probability, confidence, and calibration describe different properties of a decision. Values are illustrative and are not measured provider results
Image support gives OpenAI a wider starting point
OpenAI has confirmed that Decisions API can receive text or images as context.
This expands the available use cases.
An ecommerce platform could classify a product listing using its description and images. An insurance application could route a claim using a written report and damage photographs. A browser agent could choose its next action using a screenshot. A moderation system could evaluate visual content against declared policy outcomes.
The Jev interface covered in our original analysis focuses on application state and typed questions. Its documented use cases, listed on the OpenRouter model page and Vercel AI Gateway, involve text based routing, scoring, moderation, verification, and tool selection.
OpenAI’s image support gives it an immediate advantage for workflows where the decision depends on visual evidence. The quality of that advantage will depend on image understanding accuracy, input pricing, processing time, and the number of images supported in one decision request.
Pricing could decide the market
Jev’s pricing is one of its strongest commercial arguments.
The published price for Jev 1.13 is $0.042 per million input tokens on OpenRouter, with no charge for output tokens. Cloudflare publishes the same Jev pricing. That structure suits applications making large numbers of small decisions.
OpenAI has yet to publish Decisions API pricing. GPT-6 Luna itself has published standard rates of $0.10 per million input tokens, $0.50 per million output tokens, and $0.01 per million cached input tokens for requests within the short context pricing range. OpenAI has not said whether Decisions API will use those rates or a separate pricing structure.
Several pricing approaches are possible. OpenAI could charge normal GPT-6 Luna token rates. It could introduce separate decision pricing. It could charge for input while treating the selected answer as free output. It could create a service price based on requests or evaluated questions.
The final structure will determine which workloads make economic sense.
A small price difference matters little for a few thousand decisions. It becomes significant when an agent platform, moderation service, support system, or marketplace evaluates millions of items every month. Teams should calculate the cost per successful decision. This calculation should include input, output, retries, failed requests, human review, and any additional call required to explain a result.
Whether Jev can defend its position through lower cost and higher speed, and whether OpenAI can neutralise that advantage through its own pricing and distribution, are the questions that will decide this comparison.
Speed is valuable when the decision sits in the execution path
Routing decisions often occur before an application can act. An agent must select a tool before using it. A support request must be classified before reaching the correct queue. A safety check must finish before an action receives approval. Every additional delay affects the user experience.
OpenAI presented Decisions API as a service for real time decisions. Jev also positions low latency as a central capability. A useful comparison should measure:
- Median latency - The typical case, and the number a vendor page quotes.
- Tail latency - The p95 and p99 that the slowest requests see, which is what a waiting user actually experiences.
- Performance under concurrent traffic - Whether the service holds those numbers at your own peak, measured under real concurrency.
- Timeouts and failed requests - The rate at which no decision arrives, which the application has to handle as an outcome of its own.
- Latency when several questions share the same context - Whether evaluating 5 questions about one document costs 5 round trips or 1.
- Image processing time - The added cost of visual context, which applies to Decisions API and not to a text only interface.
Those 6 answer different questions, and a provider can win on the first while losing on the second. Record the region, provider route, payload size, concurrency, retries, and whether requests are warm or cold. Run enough repeated requests to report p50, p95, and p99 latency. Record these controls alongside the measurements.
Average latency can conceal slow requests. Tail latency matters because repeated decisions can accumulate across an agent workflow. OpenRouter measured a 175 millisecond median and 270 millisecond p95 for Jev in one Banking77 evaluation. That test covered one dataset, one domain, one prompt design, one provider route, and one testing period, so teams should treat it as directional evidence.
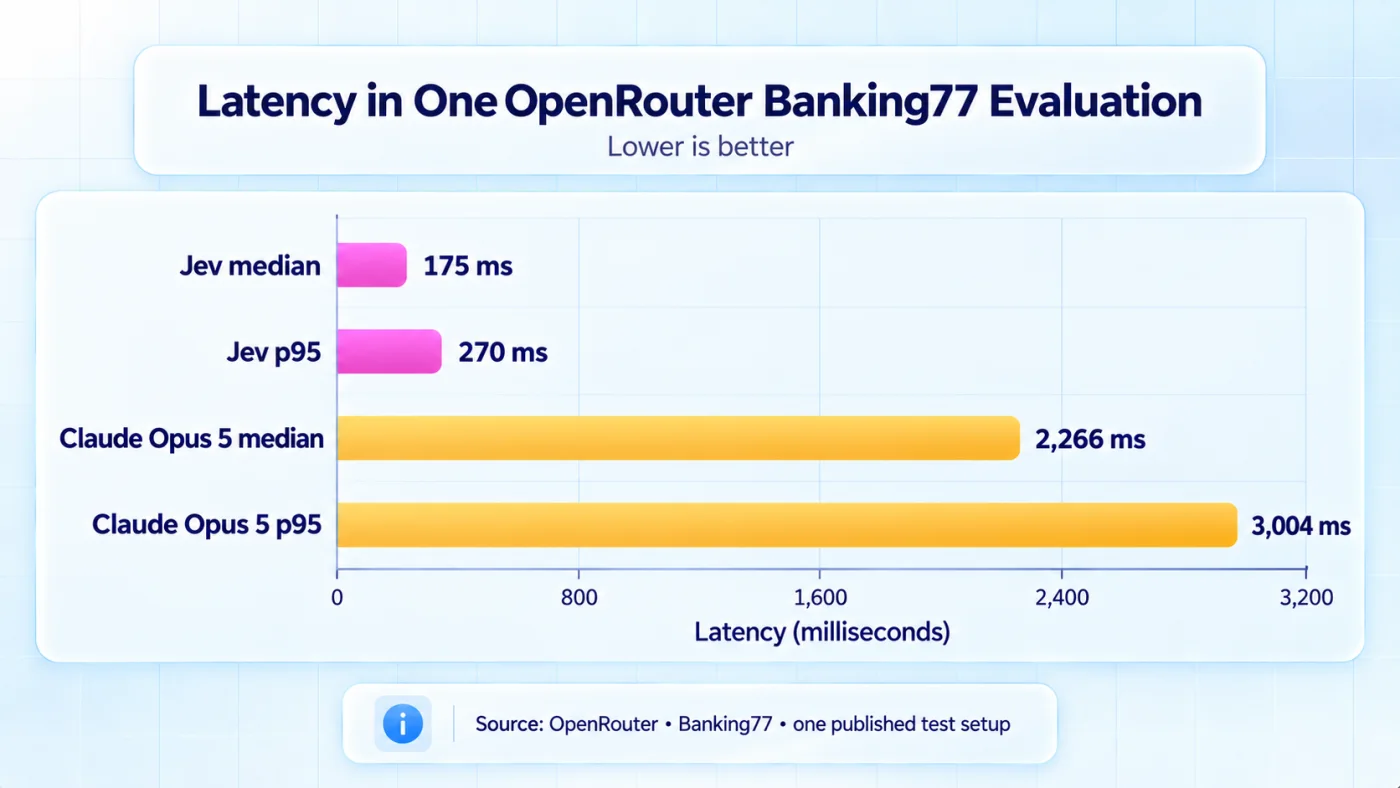
Fig 5 – OpenRouter’s Banking77 evaluation covered one dataset and one published testing setup. This is platform published evidence
Does Jev have a defensible position?
OpenAI’s entry creates serious competition for TypeSafe.
OpenAI already has extensive distribution across API products, ChatGPT, Codex, and its agent ecosystem. Existing customers may prefer to add Decisions API through a provider they already use.
Jev still has several possible advantages:
- Specialised decision training - Jev is designed around bounded judgments and calibrated outputs. That focus may produce stronger probability quality for decision workloads.
- Published economics - Jev already has transparent input pricing and free output. Teams can calculate costs before beginning an evaluation.
- Early availability - Jev can be tested today through OpenRouter, Vercel AI Gateway, and Cloudflare Workers AI, while Decisions API access is still being rolled out.
- Multiple integration routes - Jev is available through several providers, giving teams more than one way to reach the model without vendor lock in.
- Clear product identity - Jev has been presented from the beginning as a decision model. Its interface, terminology, pricing, and published evaluations are built around that purpose.
These advantages require validation with real workloads. OpenAI can apply its distribution, infrastructure, and pricing power quickly. Jev will need measurable superiority in cost, speed, calibration, accuracy, or portability.
Interface compatibility will affect competition
The decision model market will benefit from a common request format. Jev receives shared application state and a set of typed questions. Those questions can request a Choice, Score, or Noul result.
OpenAI has described user defined questions with finite predefined answers, although the complete schema remains unpublished. A compatible interface would allow teams to test providers using the same application code. An incompatible interface would require adapters and separate validation rules.
Development teams should avoid connecting business logic directly to one provider’s response structure. A small internal decision interface can define:
A small internal interface needs only 6 concepts to do this: the context being supplied, the allowed outcomes, confidence, abstention, any explanation requirement, and usage information for cost reporting. None of those are provider specific, which is the point.
Each provider can then have its own adapter. This keeps evaluations fair and makes future switching easier.
How to test OpenAI Decisions API against Jev Decision Model on one real decision
A useful evaluation begins with a real decision from the product.
- Define the decision precisely - List every permitted outcome and describe when each one should be selected. Add an abstain or review outcome where the available answers may be incomplete.
- Build a representative dataset - Include common cases, ambiguous cases, rare events, incomplete context, conflicting evidence, and examples that previously required human judgment.
- Establish the current baseline - Measure the rules engine, classifier, language model, or human workflow already making the decision.
- Test the same cases across providers - Keep the context, allowed answers, and scoring rules consistent. Record every request and response.
- Run in shadow mode - Send production cases to the decision model without allowing it to control the workflow, then compare its selections with the current system and the actual outcomes.
- Set automation thresholds - Define which results proceed automatically, which go to review, and which stop the workflow entirely.
Measure more than accuracy. Accuracy alone will rank 2 providers and will not tell a team how much of the workflow it can hand over, which is the decision the evaluation exists to support. A complete evaluation should include all 10 of these.
- Accuracy - The share of cases where the model picks the answer a reviewer would have picked.
- Calibration - Whether stated probabilities match observed outcomes across many cases.
- Abstention quality - Whether the cases it declines are the cases it would have got wrong.
- Median latency - The typical response time in the path the decision sits in.
- Tail latency - The slow requests, which set the timeout the application has to carry.
- Cost per decision - Input, output, retries and failures together, which lands well above the headline token price.
- Failure rate - How often no usable answer comes back at all.
- Human review rate - The share of traffic that still needs a person, which is what sets the saving.
- Performance after wording changes - Whether a small prompt edit moves the selections.
- Performance across text and image inputs - Measured separately, since one provider accepts both and the other accepts text.
Read together, these 10 describe how much a team can automate and at what cost. Read individually, any one of them can flatter a provider.
Beyond those 10, a rigorous evaluation should also:
- Split into a development set for prompt and threshold tuning and a separate test set for reported results
- Allow each provider’s instructions and adapter to be tuned on the development set, then freeze them before testing
- Report classwise precision, recall, confusion matrices, and the cost of specific error types
- Evaluate probability quality with
Brier score, log loss, reliability diagrams, and expected calibration error where applicable - Plot risk against coverage to show how accuracy improves as uncertain cases move to human review
- Test text and image inputs separately, since Jev’s documented interface accepts text while Decisions API accepts both
One caution on fairness. Requiring identical wording across providers can quietly favour whichever interface the prompt was written for, so the decision definition and the scoring policy are what should stay equivalent, while provider specific formatting is allowed to differ. A test that holds the formatting constant is measuring the prompt as much as the model.
Done this way the evaluation produces something a procurement conversation can actually use: a measured accuracy figure on your own cases, a calibration curve, a review rate that converts into a cost, and a latency profile taken under your own traffic. That is a stronger basis for an architecture decision than any vendor comparison published by either provider.
What OpenAI’s entry means for the wider market
OpenAI’s announcement gives decision models greater visibility. Application teams now have a clearer reason to give bounded outputs a dedicated interface while using separate model calls for generated responses, planning, and explanations.
Other model providers and AI gateways are likely to explore similar interfaces. Development frameworks may begin supporting decision requests as a distinct operation. Evaluation products may add calibration and selective automation metrics. Common conventions could emerge around context, answer sets, probabilities, abstention, and usage reporting. The result could become a competitive market containing dedicated decision models, decision interfaces powered by language models, open models, and self hosted alternatives.
Conclusion
OpenAI is entering a market that Jev helped expose. Decisions API and Jev now solve the same class of problem from 2 directions. Decisions API uses GPT-6 Luna to evaluate developer defined questions and finite possible answers from text or image context.
Jev already provides a public decision interface, typed questions, probability based answers, published pricing, and multiple integration routes. OpenAI’s distribution creates pressure for Jev, though its specialisation gives it a case to defend. Pricing, calibration, abstention, latency, and real workload accuracy will determine how the competition develops.
For development teams, the immediate task is to identify the repeated decisions inside their products and build evaluation datasets around them. Those datasets will make it possible to compare Jev, OpenAI Decisions, rules, classifiers, and future alternatives using evidence. The decision model market has moved from an emerging idea to a competitive product category.
The next release of OpenAI’s documentation will show how directly its new API challenges Jev.
Build production decision systems with Clixlogix
Clixlogix helps AI product teams identify the bounded decisions inside agents and software workflows, define provider neutral interfaces, and build evaluation datasets from real product traffic.
Our AI engineers benchmark accuracy, calibration, latency, abstention, and cost across decision models, structured output language models, classifiers, and rules. We also implement confidence based escalation, human review, observability, and shadow testing before the system controls a production workflow.
If routing, classification, scoring, moderation, or approval calls are consuming your AI budget, we can design and validate a decision system for the workload.
Talk To Our AI Engineers